Introduction
I was experimenting with vector search in SQL Server 2025 using approximately 3.8 million Hacker News articles that that I used for my talk on SQL Server-based vector search feature at EightKB. I generated two sets of embeddings from the same articles: one stored as FP32 (32-bit floating point) and the other as FP16 (16-bit floating point). Both sets contained the same articles and used DiskANN vector indexes.I used a query as below to find articles similar to a selected example.
DECLARE @QueryVector VECTOR(768, FLOAT32);-- Get the embedding of our example article.SELECT @QueryVector = embeddingFROM dbo.ArticlesEmbeddings_FP32WHERE hn_id = 18349232;-- Find the 10 most similar articles.SELECT TOP (10) e.hn_id, vs.distanceFROM VECTOR_SEARCH( TABLE = dbo.ArticlesEmbeddings_FP32 AS e, COLUMN = embedding, SIMILAR_TO = @QueryVector, METRIC = 'cosine', TOP_N = 11) AS vsWHERE e.hn_id <> 18349232ORDER BY vs.distance;
The query takes the embedding of one article and uses SQL Server’s vector index to find articles with similar embeddings. The distance value tells us how close the articles are: a smaller cosine distance means greater similarity.I then ran the equivalent query against the FP16 table, using an FP16 query vector. I expected FP16 to be faster, or at least require fewer logical reads. After all, an FP16 embedding uses roughly half the storage of an FP32 embedding.But that wasn’t always the case. Some FP16 searches were slower and performed more logical reads than the equivalent FP32 searches, although the size of embeddings were half the size of FP32.It made me wonder whether the difference had less to do with embedding size and more to do with how SQL Server builds and searches its DiskANN vector indexes.There are two possible explanations:
1. SQL Server’s FP32 and FP16 indexes report different starting nodes, based on the sys.vector_indexes DMV. Even if the graphs are nearly identical, beginning in different places could lead the search through different parts of the graph and require different amounts of work.
2. Although the graphs are similar, they are not identical. A few different connections could cause the search to discover different articles, follow different routes, and perform more or fewer comparisons.
I engaged in two experiments for this purpose.
Experiment A — Graph structure and ranking
Determine whether changing vector precision from FP32 to FP16 changes the reconstructed graph’s connections or the ranking of candidates.
Experiment B — Search traversal
Determine whether the small differences between the FP32 and FP16 reconstructed graphs cause the search to perform different amounts of work, and whether the different starting points contribute to those differences.
In this blog post, I’ll explore Experiment A. These experiments are only exploratory recreations of the DiskANN algorithm, based on what we know of its parameters, using SQL Server Graph tables. They are not a replica of the index.
As a first step, I tried to recreate DiskANN’s graph structure using SQL Server Graph tables. DiskANN algorithm has many parameters. Not all of them are exposed in the SQL Server implementation. You can view what is exposed in the build_parameters column using the query below.
SELECT i.name, vi.vector_index_type as index, vi.distance_metric, vi.build_parametersFROM sys.vector_indexes AS viJOIN sys.indexes AS i ON i.object_id = vi.object_idAND i.index_id = vi.index_id;
My results for my FP32 and FP16 indexes are below.
name index distance_metric
build_parameters
IX_ArticlesEmbeddings_FP32_Embedding DiskANN COSINE {“StartId”:”2041021″, “L”:”48″, “M”:”8″, “R”:”48″}
IX_ArticlesEmbeddings_FP16_Embedding DiskANN COSINE
{“StartId”:”5237″, “L”:”48″, “M”:”8″, “R”:”48″}
Microsoft has marked the build_parameters column as ‘for internal use only’. We don’t know how these parameters are used. But based on the algorithm, we can reasonably assume L stands for Search List/Candidate List Size, and R stands for the maximum degree of the graph index. It is unclear what M means.
To construct the simulated graph, I used the parameters reported by SQL Server’s DiskANN indexes as a starting point.
I treated R = 48 as the maximum number of outgoing connections each node could have.
I used L = 48 as the search-list size when exploring the graph, but not as a limit on the number of connections.
For graph construction, I considered up to 192 candidate neighbors (4×R) for each node, then selected the best connections using cosine distance and a pruning factor of 1.2 to avoid keeping too many similar neighbors.
I also allowed reverse-edge proposals to help connect the graph.
StartID seemed to align with hn_id, the key defined in the embedding tables, so I used that.
Imagine we have five rows in our embeddings table. Each row represents a Hacker News article and contains a 768-dimensional vector describing its content.
| embedding_id | Article | Example cosine distance from A |
| 101 | A: SQL Server indexes | 0.00 |
| 102 | B: Database performance | 0.08 |
| 103 | C: Query optimization | 0.12 |
| 104 | D: Machine learning | 0.65 |
| 105 | E: Cooking recipes | 0.91 |
Illustrative graph built from those rows may look as below.
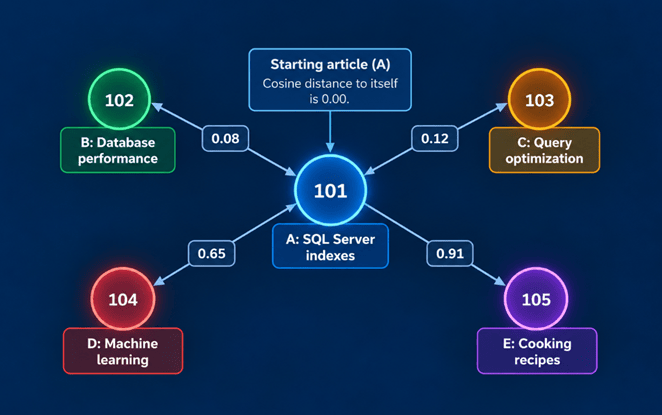
The graph-building process works as follows:
1. Create nodes: Each embedding row becomes a potential graph node, identified by its embedding_id.
2. Find candidates: For article A, our simulation considers up to 192 candidate articles and calculates their cosine distances.
3. Select connections: It uses a pruning rule with alpha = 1.2 to favor useful connections rather than simply keeping many nearly identical neighbors.
4. Apply R = 48: Article A can have at most 48 outgoing connections. In this small example, it might retain B and C because they are closely related, plus another connection that helps reach a different part of the graph.
5. Store edges: Each selected connection becomes a row in VectorSearchEdgeFP32 or VectorSearchEdgeFP16, such as 101 → 102.
The original vector tables are as below:
USE [HackerNews]GOCREATE TABLE [dbo].[HackerNewsStories]([hn_id] [int] NOT NULL,[type_value] [nvarchar](50) NULL,[by_user] [nvarchar](200) NULL,[time_value] [bigint] NULL,[title] [nvarchar](max) NULL,[url] [nvarchar](max) NULL,[score] [int] NULL,[descendants] [int] NULL,[actualtext] [nvarchar](max) NULL,CONSTRAINT [PK_HackerNewsStories_hn_id] PRIMARY KEY CLUSTERED([hn_id] ASC)WITH (PAD_INDEX = OFF, STATISTICS_NORECOMPUTE = OFF, IGNORE_DUP_KEY = OFF, ALLOW_ROW_LOCKS = ON, ALLOW_PAGE_LOCKS = ON, OPTIMIZE_FOR_SEQUENTIAL_KEY = OFF) ON [PRIMARY]) ON [PRIMARY] TEXTIMAGE_ON [PRIMARY]CREATE TABLE [dbo].[ArticlesEmbeddings_FP16]([embedding_id] [int] IDENTITY(1,1) NOT NULL,[hn_id] [bigint] NOT NULL,[n_tokens] [int] NOT NULL,[embedding] [vector](768, float16) NULL,[created_at] [datetime2](7) NOT NULL,PRIMARY KEY CLUSTERED([embedding_id] ASC)WITH (PAD_INDEX = OFF, STATISTICS_NORECOMPUTE = OFF, IGNORE_DUP_KEY = OFF, ALLOW_ROW_LOCKS = ON, ALLOW_PAGE_LOCKS = ON, OPTIMIZE_FOR_SEQUENTIAL_KEY = OFF) ON [PRIMARY]) ON [PRIMARY]GOCREATE TABLE [dbo].[ArticlesEmbeddings_FP32]([embedding_id] [int] IDENTITY(1,1) NOT NULL,[hn_id] [bigint] NOT NULL,[n_tokens] [int] NOT NULL,[embedding] [vector](768, float32) NULL,[created_at] [datetime2](7) NOT NULL,PRIMARY KEY CLUSTERED([embedding_id] ASC)WITH (PAD_INDEX = OFF, STATISTICS_NORECOMPUTE = OFF, IGNORE_DUP_KEY = OFF, ALLOW_ROW_LOCKS = ON, ALLOW_PAGE_LOCKS = ON, OPTIMIZE_FOR_SEQUENTIAL_KEY = OFF) ON [PRIMARY]) ON [PRIMARY]GO
The graph table equivalents are as below:
USE [HackerNews]GOSET ANSI_NULLS ONGOSET QUOTED_IDENTIFIER ONGOCREATE TABLE [dbo].[VectorSearchNode]([GraphVectorID] [int] IDENTITY(1,1) NOT NULL,[hn_id] [bigint] NOT NULL,[FP32EmbeddingID] [int] NOT NULL,[FP16EmbeddingID] [int] NOT NULL,[Embedding32] [vector](768, float32) NOT NULL,[Embedding16] [vector](768, float16) NOT NULL,[IsQuery] [bit] NOT NULL,[InFP32Result] [bit] NOT NULL,[FP32Rank] [int] NULL,[FP32ResultDistance] [float] NULL,[InFP16Result] [bit] NOT NULL,[FP16Rank] [int] NULL,[FP16ResultDistance] [float] NULL,CONSTRAINT [PK_VectorSearchNode] PRIMARY KEY CLUSTERED([GraphVectorID] ASC)WITH (PAD_INDEX = OFF, STATISTICS_NORECOMPUTE = OFF, IGNORE_DUP_KEY = OFF, ALLOW_ROW_LOCKS = ON, ALLOW_PAGE_LOCKS = ON, OPTIMIZE_FOR_SEQUENTIAL_KEY = OFF) ON [PRIMARY],CONSTRAINT [UQ_VectorSearchNode_hn_id] UNIQUE NONCLUSTERED([hn_id] ASC)WITH (PAD_INDEX = OFF, STATISTICS_NORECOMPUTE = OFF, IGNORE_DUP_KEY = OFF, ALLOW_ROW_LOCKS = ON, ALLOW_PAGE_LOCKS = ON, OPTIMIZE_FOR_SEQUENTIAL_KEY = OFF) ON [PRIMARY])AS NODE ON [PRIMARY]GOCREATE TABLE [dbo].[VectorSearchEdgeFP32]([FromEmbeddingID] [int] NOT NULL,[ToEmbeddingID] [int] NOT NULL,[ToHnId] [bigint] NOT NULL,[NeighborRank] [int] NOT NULL,[SourceDistance] [float] NOT NULL,CONSTRAINT [PK_VectorSearchEdgeFP32] PRIMARY KEY CLUSTERED([FromEmbeddingID] ASC,[ToEmbeddingID] ASC)WITH (PAD_INDEX = OFF, STATISTICS_NORECOMPUTE = OFF, IGNORE_DUP_KEY = OFF, ALLOW_ROW_LOCKS = ON, ALLOW_PAGE_LOCKS = ON, OPTIMIZE_FOR_SEQUENTIAL_KEY = OFF) ON [PRIMARY]) ON [PRIMARY]GOCREATE TABLE [dbo].[VectorSearchEdgeFP16]([FromEmbeddingID] [int] NOT NULL,[ToEmbeddingID] [int] NOT NULL,[ToHnId] [bigint] NOT NULL,[NeighborRank] [int] NOT NULL,[SourceDistance] [float] NOT NULL,CONSTRAINT [PK_VectorSearchEdgeFP16] PRIMARY KEY CLUSTERED([FromEmbeddingID] ASC,[ToEmbeddingID] ASC)WITH (PAD_INDEX = OFF, STATISTICS_NORECOMPUTE = OFF, IGNORE_DUP_KEY = OFF, ALLOW_ROW_LOCKS = ON, ALLOW_PAGE_LOCKS = ON, OPTIMIZE_FOR_SEQUENTIAL_KEY = OFF) ON [PRIMARY]) ON [PRIMARY]GO
The stored procedure used to construct the graphs and populate it from the original embedding tables is as below – the procedure is the same for FP16 and FP32, only points to the appropriate tables.
USE [HackerNews]GOET ANSI_NULLS ONGOSET QUOTED_IDENTIFIER ONGOCREATE PROCEDURE [dbo].[BuildRobustNeighborsFP16_ExpA](@FromEmbeddingID int,@CandidatePool int = 192,@R int = 48,@Alpha float = 1.2)ASBEGINSET NOCOUNT ON;SET XACT_ABORT ON;IF @CandidatePool > 256THROW 55101, 'CandidatePool must be <= 256.', 1;IF @R > @CandidatePoolTHROW 55102, 'R cannot exceed CandidatePool.', 1;/*==============================================================Check existing cached adjacency==============================================================*/DECLARE @ExistingBuiltAt datetime2(7);SELECT@ExistingBuiltAt = BuiltAtFROM dbo.VectorAdjacencyBuildState_ExpAWHERE Precision = 'FP16'AND FromEmbeddingID = @FromEmbeddingIDAND CandidatePool = @CandidatePoolAND R = @RAND Alpha = @Alpha;/*If this node has already been built using the same parameters,reuse it unless a newer reciprocal-edge proposal exists.*/IF @ExistingBuiltAt IS NOT NULLAND NOT EXISTS(SELECT 1FROM dbo.VectorReverseProposalFP16_ExpAWHERE OwnerEmbeddingID = @FromEmbeddingIDAND CreatedAt > @ExistingBuiltAt)BEGINRETURN;END;/*==============================================================Rebuild this node's adjacency list==============================================================*/DELETE FROM dbo.VectorSearchEdgeFP16_ExpAWHERE FromEmbeddingID = @FromEmbeddingID;DELETE FROM dbo.VectorAdjacencyBuildState_ExpAWHERE Precision = 'FP16'AND FromEmbeddingID = @FromEmbeddingID;/*==============================================================Retrieve source vector==============================================================*/DECLARE @SourceVector vector(768,float16);SELECT@SourceVector = embeddingFROM dbo.ArticlesEmbeddings_FP16WHERE embedding_id = @FromEmbeddingID;IF @SourceVector IS NULLTHROW 55103, 'FP16 source embedding not found.', 1;/*==============================================================Candidate poolCandidate generation uses VECTOR_SEARCH against the completeFP16 table/index.TOP_N = 257 gives us:up to 256 candidate nodes+ source vector itselfWe retain @CandidatePool candidates after removing source.==============================================================*/CREATE TABLE #Pool(CandidateEmbeddingID int NOT NULL PRIMARY KEY,CandidateHnId bigint NOT NULL,CandidateVector vector(768,float16) NOT NULL,DistanceFromSource float NOT NULL,IsActive bit NOT NULL);INSERT #Pool(CandidateEmbeddingID,CandidateHnId,CandidateVector,DistanceFromSource,IsActive)SELECT TOP (@CandidatePool)E.embedding_id,E.hn_id,E.embedding,VS.distance,1FROM VECTOR_SEARCH(TABLE = dbo.ArticlesEmbeddings_FP16 AS E,COLUMN = embedding,SIMILAR_TO = @SourceVector,METRIC = 'cosine',TOP_N = 257) AS VSWHERE E.embedding_id <> @FromEmbeddingIDORDER BYVS.distance,E.embedding_id;/*==============================================================Add reciprocal-edge proposalsIf another node previously selected:OtherNode -> ThisNodethen we consider:ThisNode -> OtherNodeas an additional candidate.==============================================================*/INSERT #Pool(CandidateEmbeddingID,CandidateHnId,CandidateVector,DistanceFromSource,IsActive)SELECTE.embedding_id,E.hn_id,E.embedding,VECTOR_DISTANCE('cosine',@SourceVector,E.embedding),1FROM dbo.VectorReverseProposalFP16_ExpA AS RPINNER JOIN dbo.ArticlesEmbeddings_FP16 AS EON E.embedding_id = RP.CandidateEmbeddingIDLEFT JOIN #Pool AS PON P.CandidateEmbeddingID = E.embedding_idWHERE RP.OwnerEmbeddingID = @FromEmbeddingIDAND E.embedding_id <> @FromEmbeddingIDAND P.CandidateEmbeddingID IS NULL;/*==============================================================Robust pruningRepeatedly:1. Select closest remaining candidate U.2. Add U as a graph edge.3. Remove U from candidate pool.4. Remove candidates V that are sufficiently representedby U.Approximate pruning rule:Alpha * distance(U,V)<=distance(Source,V)Continue until:R neighbors selectedORno candidates remain.==============================================================*/DECLARE @SelectedCount int = 0;DECLARE @CurrentRank int = 0;DECLARE @SelectedEmbeddingID int;DECLARE @SelectedHnId bigint;DECLARE @SelectedDistance float;DECLARE @SelectedVector vector(768,float16);WHILE @SelectedCount < @RBEGINSET @SelectedEmbeddingID = NULL;/*----------------------------------------------------------Pick closest active candidate----------------------------------------------------------*/SELECT TOP (1)@SelectedEmbeddingID =P.CandidateEmbeddingID,@SelectedHnId =P.CandidateHnId,@SelectedVector =P.CandidateVector,@SelectedDistance =P.DistanceFromSourceFROM #Pool AS PWHERE P.IsActive = 1ORDER BYP.DistanceFromSource,P.CandidateEmbeddingID;IF @SelectedEmbeddingID IS NULLBREAK;SET @SelectedCount += 1;SET @CurrentRank += 1;/*----------------------------------------------------------Add selected neighbor to graph----------------------------------------------------------*/INSERT dbo.VectorSearchEdgeFP16_ExpA(FromEmbeddingID,ToEmbeddingID,ToHnId,NeighborRank,SourceDistance)VALUES(@FromEmbeddingID,@SelectedEmbeddingID,@SelectedHnId,@CurrentRank,@SelectedDistance);/*----------------------------------------------------------Selected candidate is consumed----------------------------------------------------------*/UPDATE #PoolSET IsActive = 0WHERE CandidateEmbeddingID =@SelectedEmbeddingID;/*----------------------------------------------------------Robust prune remaining candidatesU = selected neighborV = remaining candidateRemove V when:Alpha * distance(U,V)<=distance(Source,V)This is what introduces diversity compared with simplykeeping the nearest 48 vectors.----------------------------------------------------------*/UPDATE PSET IsActive = 0FROM #Pool AS PWHERE P.IsActive = 1AND(@Alpha *VECTOR_DISTANCE('cosine',@SelectedVector,P.CandidateVector))<= P.DistanceFromSource;END;/*==============================================================Generate reciprocal-edge proposalsEvery selected:Source -> Neighborproposes:Neighbor -> SourceThe proposal will be considered when Neighbor's adjacencylist is built/rebuilt.==============================================================*/INSERT dbo.VectorReverseProposalFP16_ExpA(OwnerEmbeddingID,CandidateEmbeddingID)SELECTE.ToEmbeddingID,E.FromEmbeddingIDFROM dbo.VectorSearchEdgeFP16_ExpA AS ELEFT JOIN dbo.VectorReverseProposalFP16_ExpA AS ExistingON Existing.OwnerEmbeddingID =E.ToEmbeddingIDAND Existing.CandidateEmbeddingID =E.FromEmbeddingIDWHERE E.FromEmbeddingID =@FromEmbeddingIDAND Existing.OwnerEmbeddingID IS NULL;/*==============================================================Mark adjacency list as built==============================================================*/INSERT dbo.VectorAdjacencyBuildState_ExpA(Precision,FromEmbeddingID,CandidatePool,R,Alpha,BuiltAt)VALUES('FP16',@FromEmbeddingID,@CandidatePool,@R,@Alpha,SYSUTCDATETIME());END;GO
After constructing the graph, I use L as the search-list size when navigating it. It controls how many promising candidates the simulated search keeps track of, not how many edges each node has.
R controls graph connections, while L guides graph searching. The 192-candidate pool and pruning factor are assumptions.
| Parameter | Setting |
| Matched source articles | 1,000 |
| Candidate pool | 192 |
| Maximum outgoing edges (R) | 48 |
| Pruning parameter (alpha) | 1.2 |
| Build passes | 2 |
| Query article hn_id | 18349232 |
The graph was built by calling dbo.BuildRobustNeighborsFP32_ExpA and dbo.BuildRobustNeighborsFP16_ExpA (code above) for the matched embedding IDs, using @CandidatePool = 192, @R = 48, and @Alpha = 1.2.
Tests performed
1. Graph size and overlap
The two graphs had almost the same number of edges: 45,855 for FP32 and 45,871 for FP16. Each graph had outgoing edges for all 1,000 sampled source articles. FP16 had only 16 more edges, about 0.035% more than FP32.
| Metric | FP32 | FP16 |
| Built source nodes | 1,000 | 1,000 |
| Directed edges | 45,855 | 45,871 |
| Distinct destinations | 43,151 | 43,148 |
| Average outgoing edges | 45.86 | 45.87 |
SQL: graph size
SELECT 'FP32' AS Precision, COUNT(DISTINCT FromEmbeddingID) AS BuiltSourceNodes, COUNT_BIG(*) AS TotalEdges, COUNT(DISTINCT ToEmbeddingID) AS DistinctDestinationNodesFROM dbo.VectorSearchEdgeFP32_ExpAUNION ALLSELECT 'FP16', COUNT(DISTINCT FromEmbeddingID), COUNT_BIG(*), COUNT(DISTINCT ToEmbeddingID)FROM dbo.VectorSearchEdgeFP16_ExpA;
I then compared neighbors using article hn_id, rather than embedding_id, because the identity values are not guaranteed to match between precision tables. The average Jaccard similarity was 0.9191 (91.91%).( Jaccard similarity is the number of shared neighbors divided by the number of distinct neighbors across both lists.
| Neighborhood measure | Result |
| Average shared neighbors | 43.81 |
| Average Jaccard | 91.91% |
| Minimum Jaccard | 41.18% |
| Maximum Jaccard | 100% |
Our earlier exploratory run reported 96.35% average Jaccard, but only for 143 common source articles. The revised 1,000-article matched test is the more useful comparison. The 4.44 percentage-point decrease should not be interpreted as an effect of sample size alone: the experiment population and build histories also changed.
SQL: neighborhood overlap
WITH FP32Edges AS( SELECT src.hn_id AS SourceHnId, g.ToHnId AS NeighborHnId FROM dbo.VectorSearchEdgeFP32_ExpA AS g JOIN dbo.ArticlesEmbeddings_FP32 AS src ON src.embedding_id = g.FromEmbeddingID),FP16Edges AS( SELECT src.hn_id AS SourceHnId, g.ToHnId AS NeighborHnId FROM dbo.VectorSearchEdgeFP16_ExpA AS g JOIN dbo.ArticlesEmbeddings_FP16 AS src ON src.embedding_id = g.FromEmbeddingID),Combined AS( SELECT COALESCE(a.SourceHnId,b.SourceHnId) AS SourceHnId, CASE WHEN a.NeighborHnId IS NULL THEN 0 ELSE 1 END AS InFP32, CASE WHEN b.NeighborHnId IS NULL THEN 0 ELSE 1 END AS InFP16 FROM FP32Edges AS a FULL JOIN FP16Edges AS b ON a.SourceHnId=b.SourceHnId AND a.NeighborHnId=b.NeighborHnId),PerNode AS( SELECT SourceHnId, SUM(InFP32) AS N32, SUM(InFP16) AS N16, SUM(CASE WHEN InFP32=1 AND InFP16=1 THEN 1 ELSE 0 END) AS Shared, COUNT(*) AS UnionCount FROM Combined GROUP BY SourceHnId)SELECT COUNT(*) AS ComparedNodes, CAST(AVG(1.0*N32) AS decimal(10,2)) AS AvgFP32Neighbors, CAST(AVG(1.0*N16) AS decimal(10,2)) AS AvgFP16Neighbors, CAST(AVG(1.0*Shared) AS decimal(10,2)) AS AvgSharedNeighbors, CAST(AVG(1.0*Shared/NULLIF(UnionCount,0)) AS decimal(10,4)) AS AvgJaccardSimilarity, CAST(MIN(1.0*Shared/NULLIF(UnionCount,0)) AS decimal(10,4)) AS MinJaccardSimilarity, CAST(MAX(1.0*Shared/NULLIF(UnionCount,0)) AS decimal(10,4)) AS MaxJaccardSimilarityFROM PerNode;
2. Starting-article neighborhoods
The two articles associated with the reported native StartId values were more similar than the overall average. For hn_id 20594, both reconstructed graphs selected the same 48 neighbors. For hn_id 11559412, they shared 47 of 48 neighbors. The builder’s assigned order was also almost identical.
| Start article | FP32 / FP16 neighbors | Shared | Jaccard | Same rank |
| 20594 | 48 / 48 | 48 | 100.00% | 48 |
| 11559412 | 48 / 48 | 47 | 95.92% | 45 |
For the 47 shared neighbors of article 11559412, average absolute rank movement was 0.04 and the largest movement was one position. The builder’s NeighborRank is a selection order, not a recorded native DiskANN traversal order.
SQL: compare starting neighbors and ranks
WITH N32 AS( SELECT src.hn_id AS SourceHnId, g.ToHnId AS NeighborHnId, g.NeighborRank AS Rank32 FROM dbo.VectorSearchEdgeFP32_ExpA AS g JOIN dbo.ArticlesEmbeddings_FP32 AS src ON src.embedding_id=g.FromEmbeddingID WHERE src.hn_id IN (20594,11559412)),N16 AS( SELECT src.hn_id AS SourceHnId, g.ToHnId AS NeighborHnId, g.NeighborRank AS Rank16 FROM dbo.VectorSearchEdgeFP16_ExpA AS g JOIN dbo.ArticlesEmbeddings_FP16 AS src ON src.embedding_id=g.FromEmbeddingID WHERE src.hn_id IN (20594,11559412)),C AS( SELECT COALESCE(a.SourceHnId,b.SourceHnId) AS SourceHnId, a.Rank32,b.Rank16 FROM N32 AS a FULL JOIN N16 AS b ON a.SourceHnId=b.SourceHnId AND a.NeighborHnId=b.NeighborHnId)SELECT SourceHnId, COUNT(Rank32) AS FP32Neighbors, COUNT(Rank16) AS FP16Neighbors, SUM(CASE WHEN Rank32 IS NOT NULL AND Rank16 IS NOT NULL THEN 1 ELSE 0 END) AS SharedNeighbors, SUM(CASE WHEN Rank32=Rank16 THEN 1 ELSE 0 END) AS SameRankCount, CAST(AVG(CASE WHEN Rank32 IS NOT NULL AND Rank16 IS NOT NULL THEN 1.0*ABS(Rank32-Rank16) END) AS decimal(10,2)) AS AvgAbsoluteRankDifference, MAX(CASE WHEN Rank32 IS NOT NULL AND Rank16 IS NOT NULL THEN ABS(Rank32-Rank16) END) AS MaxAbsoluteRankDifferenceFROM C GROUP BY SourceHnId ORDER BY SourceHnId;
3. Distance differences at starting articles
For shared source-to-neighbor edges, FP16 and FP32 cosine distances differed by only a few millionths. These distances describe edges in our reconstructed graph; they are not distances from the search query.
| Start article | Avg absolute difference | Max absolute difference | Avg relative difference |
| 20594 | 0.0000046343 | 0.0000136495 | 0.002764% |
| 11559412 | 0.0000059630 | 0.0000152588 | 0.002975% |
SQL: compare stored edge distances
4. Ranking by distance to the query
A search decides which candidate looks promising using its distance to the query, not its distance to the node that supplied the edge. I therefore used query article 18349232 to calculate query-relative cosine distances in both precisions.
At the two starting articles, every candidate kept the same query-relative rank: 48 of 48 around article 20594, and 49 of 49 in the union of the two neighbor lists around article 11559412. The average absolute query-distance differences were 0.0000094548 and 0.0000083179, respectively.
SQL: query ranking at both starting articles
WITH N32 AS( SELECT src.hn_id AS SourceHnId, g.ToHnId AS NeighborHnId, g.SourceDistance AS D32 FROM dbo.VectorSearchEdgeFP32_ExpA AS g JOIN dbo.ArticlesEmbeddings_FP32 AS src ON src.embedding_id=g.FromEmbeddingID WHERE src.hn_id IN (20594,11559412)),N16 AS( SELECT src.hn_id AS SourceHnId, g.ToHnId AS NeighborHnId, g.SourceDistance AS D16 FROM dbo.VectorSearchEdgeFP16_ExpA AS g JOIN dbo.ArticlesEmbeddings_FP16 AS src ON src.embedding_id=g.FromEmbeddingID WHERE src.hn_id IN (20594,11559412))SELECT a.SourceHnId, COUNT(*) AS SharedNeighbors, CAST(AVG(ABS(a.D32-b.D16)) AS decimal(18,10)) AS AvgAbsoluteDistanceDifference, CAST(MAX(ABS(a.D32-b.D16)) AS decimal(18,10)) AS MaxAbsoluteDistanceDifference, CAST(AVG(CASE WHEN a.D32<>0 THEN 100.0*ABS(a.D32-b.D16)/ABS(a.D32) END) AS decimal(18,6)) AS AvgRelativeDifferencePctFROM N32 AS a JOIN N16 AS bON a.SourceHnId=b.SourceHnId AND a.NeighborHnId=b.NeighborHnIdGROUP BY a.SourceHnId ORDER BY a.SourceHnId;
5. Finally, I repeated the ranking test across all 1,000 source neighborhoods, comparing only candidates present in both graphs. This isolates distance-order changes from differences in candidate membership.
| Ranking measure across all 1,000 neighborhoods | Result |
| Shared candidate occurrences | 43,813 |
| Same-rank candidate occurrences | 43,648 |
| Same-rank percentage | 99.6234% |
| Nodes with identical ranking | 920 |
| Nodes with at least one rank difference | 80 |
| Largest rank displacement | 2 |
Only 165 of 43,813 shared candidate occurrences changed position. These are occurrences within source neighborhoods, not necessarily 165 distinct articles.
SQL: query ranking across the sample
DECLARE @Query32 vector(768,float32), @Query16 vector(768,float16);SELECT @Query32=embedding FROM dbo.ArticlesEmbeddings_FP32 WHERE hn_id=18349232;SELECT @Query16=embedding FROM dbo.ArticlesEmbeddings_FP16 WHERE hn_id=18349232;WITH SharedNeighbors AS( SELECT s.hn_id AS SourceHnId,g32.ToHnId AS CandidateHnId FROM dbo.VectorGraphSample AS s JOIN dbo.ArticlesEmbeddings_FP32 AS e32 ON e32.hn_id=s.hn_id JOIN dbo.ArticlesEmbeddings_FP16 AS e16 ON e16.hn_id=s.hn_id JOIN dbo.VectorSearchEdgeFP32_ExpA AS g32 ON g32.FromEmbeddingID=e32.embedding_id JOIN dbo.VectorSearchEdgeFP16_ExpA AS g16 ON g16.FromEmbeddingID=e16.embedding_id AND g16.ToHnId=g32.ToHnId),Distances AS( SELECT n.SourceHnId,n.CandidateHnId, VECTOR_DISTANCE('cosine',@Query32,e32.embedding) AS D32, VECTOR_DISTANCE('cosine',@Query16,e16.embedding) AS D16 FROM SharedNeighbors AS n JOIN dbo.ArticlesEmbeddings_FP32 AS e32 ON e32.hn_id=n.CandidateHnId JOIN dbo.ArticlesEmbeddings_FP16 AS e16 ON e16.hn_id=n.CandidateHnId),Ranked AS( SELECT *, ROW_NUMBER() OVER (PARTITION BY SourceHnId ORDER BY D32,CandidateHnId) AS Rank32, ROW_NUMBER() OVER (PARTITION BY SourceHnId ORDER BY D16,CandidateHnId) AS Rank16 FROM Distances),PerNode AS( SELECT SourceHnId,COUNT(*) AS SharedCandidates, SUM(CASE WHEN Rank32=Rank16 THEN 1 ELSE 0 END) AS SameRankCount, MAX(ABS(Rank32-Rank16)) AS MaxRankDifference FROM Ranked GROUP BY SourceHnId)SELECT COUNT(*) AS ComparedSourceNodes, SUM(SharedCandidates) AS TotalSharedCandidates, SUM(SameRankCount) AS TotalSameRankCandidates, CAST(100.0*SUM(SameRankCount)/NULLIF(SUM(SharedCandidates),0) AS decimal(10,4)) AS SameRankPercentage, SUM(CASE WHEN SameRankCount=SharedCandidates THEN 1 ELSE 0 END) AS NodesWithIdenticalRanking, SUM(CASE WHEN SameRankCount<SharedCandidates THEN 1 ELSE 0 END) AS NodesWithRankingDifferences, MAX(MaxRankDifference) AS LargestRankDisplacementFROM PerNode;
Conclusions
FP16 and FP32 produced almost the same graph density in this reconstruction. Most outgoing neighbors were shared, and the two starting articles had nearly identical local connections. For the chosen query, 99.6234% of shared candidate occurrences kept the same query-relative rank.
The practical finding is not huge, but can be useful: changing embedding precision did not substantially reorder shared candidates (in this test). It did change some edges. Those non-shared edges could still affect traversal, especially after several hops.
Scope and limitations
This experiment studies a reconstructed graph based on DiskANN parameters that are revealed. It is also not an exhaustive test – Only a sample of the original dataset was used and tests done on a couple of nodes, not all.
The two precisions use separate native indexes for candidate generation. Therefore, we cannot attribute observed edge differences to FP16 rounding alone. I did not reproduce undocumented native build behavior, and I did not implement the native index parameter M because it is undocumented and its purpose is unknown. The L = 48 value belongs to the planned traversal simulation, not the graph-construction procedure.
The rank-agreement percentage is conditional on neighbors being shared. It does not include candidates found only in one graph, nor does it show the exact order of any native search.
Next experiment
I will run a four-way controlled traversal: each reconstructed graph (FP32 and FP16) starting from each reported starting article (11559412 and 20594), using query 18349232 and the same simulated frontier limit L = 48. It is expected to find expanded nodes, candidates evaluated, and attempts to expand destinations that lack adjacency lists. This will help us understand starting-point effects from graph/precision effects within the reconstruction.
